AZ-400 Implement Continuous Feedback
The loop: read production, feed back into planning
Implement Continuous Feedback — MOC
MS Learn path: Implement continuous feedback · The loop closes: learn from production, feed back into planning.
Map / Canvas
The core idea
The release doesn’t end at deployment — it starts the observe → learn → plan cycle. Feedback is collected continuously from production and feeds the next iteration:
- Collect telemetry → Azure Monitor (infrastructure) + Application Insights (application).
- Understand users → user analytics (behavior) + feature usage (adoption).
- Detect problems proactively → synthetic testing (availability) + alerting (notifications).
- Act → insights become backlog/work items, closing the feedback loop of continuous feedback.
Modules in this path
- Introduction to continuous feedback
- Telemetry and monitoring (Azure Monitor & App Insights)
- Usage analytics: user behavior
- Synthetic testing and alerting
Concepts (linked from here)
continuous-feedback · feedback-loop · telemetry · Azure Monitor · Application Insights · user-analytics · feature-usage · synthetic-testing · alerting · devops-flow-metrics
Skills measured (exam blueprint)
- Design and configure monitoring for applications and infrastructure (Azure Monitor, Application Insights).
- Implement continuous feedback by using telemetry, user/usage analytics, and availability (synthetic) tests.
- Turn insights into actionable alerts and feed findings back into planning → release improvement.
Practice
Required lab evidence: Instrument a training service or sample telemetry source, create an availability test and an alert routed to a test action group, then explain whether Azure Monitor or Application Insights owns each signal. Remove notification endpoints and training resources afterward.
Practice questions
- az400-q-feedback-001 — Application Insights synthetic (availability) tests
- Q: alert rule and action group
- Q: feature rollout telemetry
- Q: distributed tracing
- Q: KQL post-deployment diagnosis
- Q: failed-deployment notification
Cross-module lab
Conceptual checkpoint
Explain the sequence in this path using one workload scenario: identify the boundary being changed, the identity or tool acting on it, the expected evidence, and the failure that would change your decision.
Sources and re-audit
- AZ-400 course overview, checked 2026-08-31.
- AZ-400 study guide, checked 2026-08-31.
Re-audit when the AZ-400 course path, study-guide effective date, or the services and permissions taught here change.
Introduction to Continuous Feedback
Overview
Why “implement continuous feedback” is a core loop in the DevOps lifecycle. Releases don’t end when code ships — they start the observe → learn → plan cycle that makes the next release better.
Units
- Why continuous feedback matters
- What feedback is collected and acted on
- The tools that enable the loop
- How feedback feeds planning and delivery
Concepts introduced
- continuous-feedback — the practice of collecting and acting on production signals.
- feedback-loop — the cycle that turns data into the next planned work.
- telemetry — the raw signals (metrics, logs, traces) feeding the loop.
- azure-monitor and application-insights ground the loop in real Azure tooling.
Key terms & commands
- Monitoring vs feedback — monitoring observes; feedback changes what you build next.
- Tools map: Azure Monitor (infrastructure), Application Insights (application), Azure Boards (work items from insights).
Hands-on
- Identify which telemetry (infra vs app) to collect for a sample scenario.
- Sketch a feedback loop: collection → analysis → backlog → delivery.
Exam focus
- Know the two feedback dimensions: application/system and user/behavior.
- Recognize that telemetry/insights must feed the backlog (a loop), not just be displayed.
Related
Telemetry and Monitoring
Overview
Collecting and analyzing telemetry from infrastructure and applications so you can measure performance, availability, and health — the observation half of continuous feedback.
Units
- Instrument applications and infrastructure for telemetry
- Azure Monitor metrics, logs, and activity log
- Application Insights application telemetry & dependencies
- Querying telemetry (KQL) and building workbooks/dashboards
Concepts introduced
- telemetry — metrics, logs, traces, and usage signals.
- Azure Monitor — unified platform for infrastructure telemetry (metrics, logs, activity).
- Application Insights — application/code-level telemetry (requests, dependencies, exceptions, traces).
- Log Analytics — the KQL-queryable store behind logs and App Insights.
- Alerts — turning stored telemetry into proactive notifications.
Key terms & commands
- Three Azure Monitor sinks: Metrics, Activity Log, Log Analytics.
- Instrument the app with the App Insights SDK to collect request/dependency/exception telemetry.
- Query telemetry with KQL into workbooks and dashboards.
Hands-on
- Add Application Insights to an app and view request/failure telemetry.
- Query App Insights data with KQL and build a workbook.
Exam focus
- Differentiate infrastructure (Azure Monitor) vs application (App Insights) telemetry.
- Know App Insights data lives in a Log Analytics workspace and is KQL-queryable.
Related
telemetry · azure-monitor · application-insights · log-analytics · alerting · Path MOC
Usage Analytics: Understanding User Behavior
Overview
Using application telemetry to understand how real users interact with your product — behavior, feature adoption, and satisfaction — and turning that understanding into product decisions. This is the user side of continuous feedback.
Units
- Collecting user/usage telemetry
- Analyzing page views, sessions, funnels, and engagement
- Measuring feature adoption and drop-off
- Feeding insights into the backlog
Concepts introduced
- user-analytics — behavioral insights (page views, sessions, funnels, retention).
- feature-usage — which features are adopted/used (product-adoption lens).
- Application Insights — the instrumentation source for user telemetry.
- feedback-loop — how usage insights become planned work.
Key terms & commands
- Track custom events (e.g. “feature used”) in App Insights for adoption measurement.
- Pair adoption telemetry with feature flags: ship to a subset, measure, then roll out or kill.
- Analyze usage via KQL over App Insights data.
Hands-on
- Instrument custom events and build a usage/funnel query.
- Use feature-usage data to make a “keep / expose / retire” decision.
Exam focus
- User analytics = how users behave; feature usage = which features get used.
- Usage telemetry is only valuable when it feeds planning (the feedback loop).
Related
user-analytics · feature-usage · application-insights · feedback-loop · Path MOC
Reliability: Synthetic Testing and Alerting
Overview
Proactively verifying availability and turning telemetry into actionable notifications — the detection half of continuous feedback that surfaces problems before (or as soon as) they impact users.
Units
- Validating application availability with synthetic tests
- Configuring Azure Monitor alert rules and action groups
- Severity, dynamic thresholds, and anomaly detection
- Responding to alerts and feeding findings back
Concepts introduced
- synthetic-testing — proactive, scripted availability checks from global locations.
- alerting — rule = signal + condition + action group.
- Application Insights — availability/availability tests (URL ping, standard, multi-step).
- Azure Monitor — alert rules and action groups based notifications.
Key terms & commands
- Availability tests in App Insights: URL ping (basic), standard (request + dependency), multi-step (recorded journey).
- An alert rule combines a signal (metric/log/availability) with a condition, and fires an action group (email, SMS, webhook/ITSM).
- Tests run from multiple global locations on a schedule.
Hands-on
- Create an App Insights availability (URL ping) test and an alert on failure.
- Define an alert rule + action group for a metric threshold.
Exam focus
- Synthetic = proactive availability (“is it up?”), telemetry = reactive/real-user.
- Know the alert anatomy: rule → signal + condition → action group.
- Availability-test failure is a common alert source.
Related
synthetic-testing · alerting · application-insights · azure-monitor · Path MOC
Core / Loop
Continuous Feedback
What it is
Continuous feedback is the practice of continuously collecting, analyzing, and acting on signals about how a system and its users behave in production, then feeding what you learn back into planning and development. It is one of the core DevOps practices that closes the loop between shipping software and understanding whether that software actually delivers value.
Why it exists
A deployment is not the end of the cycle — it is the start of the next one. Continuous feedback exists so teams:
- Learn from real users and real production data, not assumptions.
- Detect problems, regressions, and unmet needs early.
- Turn monitoring/telemetry into priorities and work items for the next iteration.
It directly powers continuous improvement: release → observe → learn → plan → release again.
Key ideas
- Feedback is two-sided: application/system feedback (performance, errors, availability) and user feedback (usage, satisfaction, feature adoption).
- It pairs automated telemetry (telemetry, Azure Monitor, Application Insights, synthetic-testing) with human signals (surveys, NPS, support tickets, work item feedback).
- Great feedback is actionable — raw data is not feedback until it changes what you build next (feeds a feedback-loop).
- Funnel ideas into a backlog / work items so insights become features, fixes, or rollbacks.
Exam notes
- AZ-400 treats “implement continuous feedback” as a distinct path: collect and use feedback to prioritize and improve releases.
- Know the tools in the feedback toolkit: Azure Monitor (infrastructure), Application Insights (application), Azure Monitor logs/metrics, and Azure Boards (acting on feedback as work items).
- The exam emphasizes the loop: monitoring data and user insights must feed back into planning/delivery, not just be displayed.
Related
feedback-loop · telemetry · azure-monitor · application-insights · user-analytics · feature-usage · alerting · synthetic-testing
📘 Source: Microsoft Learn — Continuous Feedback
Feedback Loop
What it is
A feedback loop is the structured cycle in which signals about a deployed system and its users are collected, analyzed, prioritized, and turned into the next planned work — so each release makes the product measurably better. It is the mechanism that operationalizes continuous feedback.
Why it exists
Insights that never change what you build are worthless. The feedback loop exists to make improvement systematic and continuous: rather than shipping and hoping, teams institutionalize “observe → learn → act → re-observe” so quality and value ratchet upward release over release.
Key ideas
- Close the loop:
- Collect — telemetry, App Insights, alerts, user analytics, surveys/NPS, tickets.
- Analyze — query logs (KQL), review dashboards/workbooks, triage bugs & enhancement requests.
- Prioritize — turn insights into PBI/bug/feature work items in a backlog.
- Deliver — plan the work into the next iteration; re-observe the impact.
- A short loop (e.g. fast dashboard/alerts) enables rapid detection; a planning loop (backlog → release) applies learnings at scale.
- Feedback quality matters as much as volume — the loop filters noise into actionable decisions.
Exam notes
- The feedback loop is the why behind every “implement continuous feedback” tool you learn (Monitor, App Insights, Boards).
- Know the pattern: data → insight → backlog item → release → re-measure.
- The exam asks how tools connect — e.g. App Insights data becomes a work item in Azure Boards to fix or enhance.
Related
continuous-feedback · telemetry · user-analytics · feature-usage · alerting · synthetic-testing
📘 Source: Microsoft Learn — Feedback Loop
Telemetry
What it is
Telemetry is evidence a system emits about what it is doing: numeric measurements, log events, request traces, dependency calls, or usage signals. It is the raw material for monitoring and diagnosis, not the diagnosis itself.
Why it exists
Without telemetry, a team is forced to guess why a service is slow or failing. With useful telemetry, it can measure a symptom, find affected requests, correlate events, alert the right people, and test whether a fix worked.
Key ideas
- Kinds of telemetry:
- Sources differ. Azure resources emit platform data through Azure Monitor; application code can emit application telemetry through Application Insights or an instrumentation library.
- A path is needed. Telemetry must be emitted, collected, stored, queried or visualized, and acted on. Not every data source is enabled or routed automatically.
Northwind example
Northwind’s checkout app records request duration, failed dependency calls, and a correlation ID. Azure Monitor supplies platform metrics for the hosting service. When checkout is slow, the team first sees a latency increase on a metric chart, then uses traces and logs tied to the correlation ID to find whether the payment dependency or the app is failing. Those signals serve different roles but describe the same customer journey.
Exam notes
- Metrics, logs, traces, and events answer different questions; choose the signal before choosing the chart or alert.
- Platform telemetry and application telemetry can be correlated, but one does not replace the other.
- Telemetry becomes useful when it supports a dashboard, alert, or feedback loop.
Related
continuous-feedback · azure-monitor · application-insights · azure-monitor-metrics · log-analytics · alerting · feedback-loop
📘 Source: Microsoft Learn — Telemetry
Azure Tooling
Azure Monitor
What it is
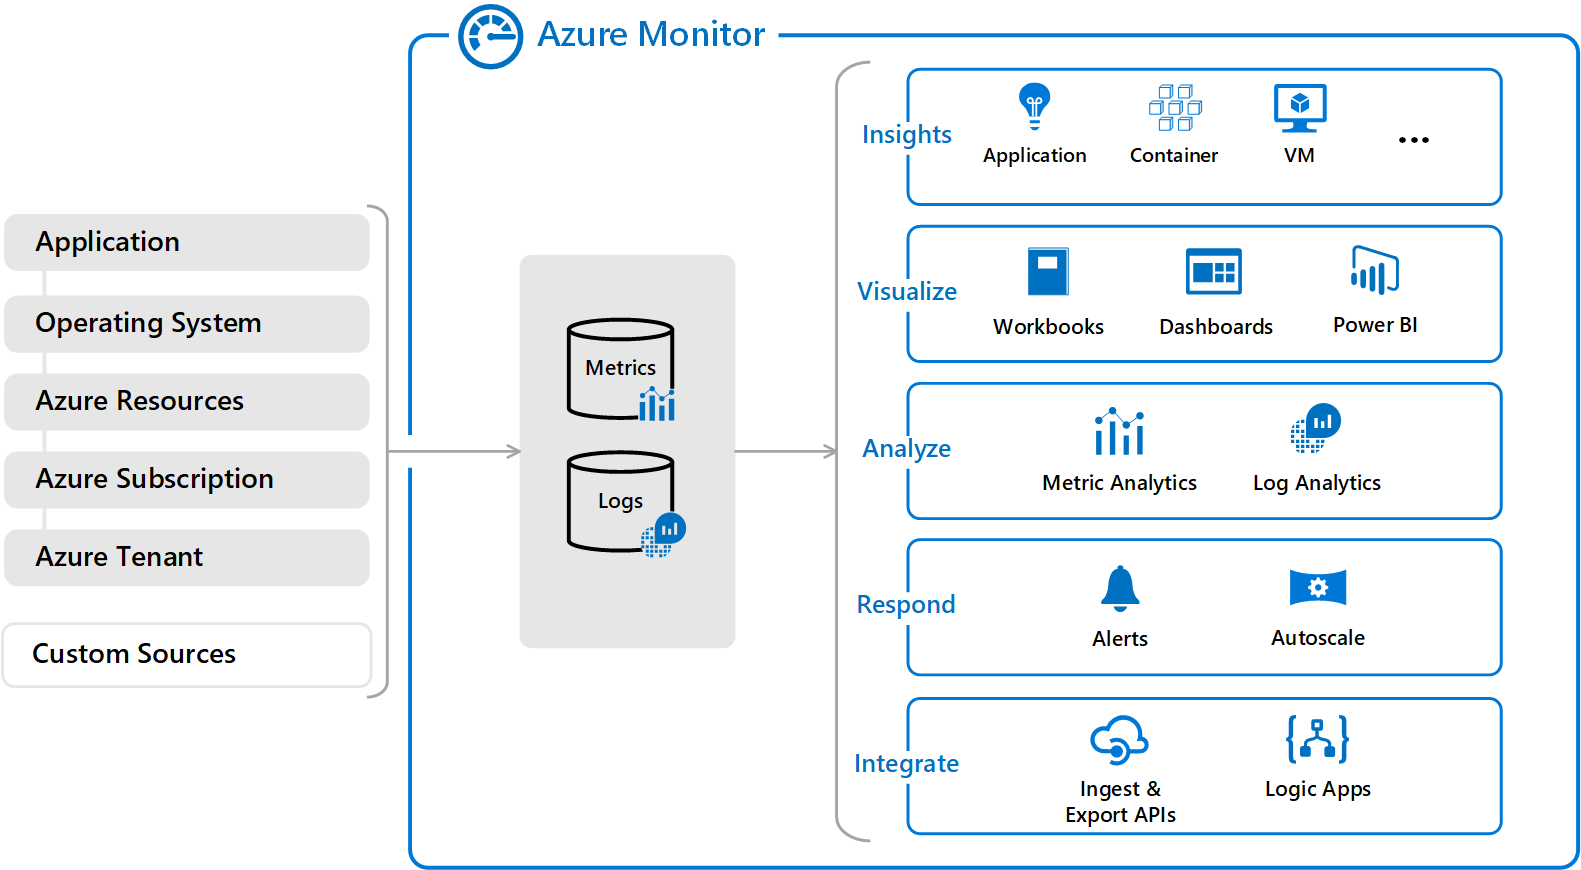
Azure Monitor is Azure’s observability service: it collects and analyzes telemetry, the evidence a system produces about what it is doing. Telemetry can be a number, a log record, an event, or a trace through an application. Azure Monitor helps people see whether a workload is healthy, investigate a problem, and notify or automate a response.
Why it exists
Every resource generates telemetry, but raw data is useless. You need a central place to (1) collect telemetry, (2) store it durably, (3) query/visualize it, and (4) react when something is wrong. Without Azure Monitor you’d have hundreds of disconnected portals per resource.
Key ideas
- Metrics are numeric measurements over time, such as CPU percentage or request count. Use them to spot trends and quick threshold conditions.
- Logs are richer records that you query, commonly in a Log Analytics workspace with KQL. Use them to investigate “which request failed and why?”
- The Activity log records Azure management events, such as someone creating or deleting a resource. It is not the same as an application’s request log.
- Application Insights adds application-level telemetry such as requests, dependencies, exceptions, and traces.
- An alert evaluates a signal and can invoke an action group to notify people or trigger a workflow. A dashboard or workbook helps people explore the data; it does not fix the issue itself.
Northwind example
Northwind uses Azure Monitor to watch its ordering workload. A metric shows that front-end CPU is rising, Application Insights shows that checkout requests are failing after a storage dependency call, and the Activity log shows a network-rule change shortly before the failures. An alert sends the on-call team a notification through an action group. The metric tells Northwind that something changed; the logs and traces help it discover why.
Common confusion
- Azure Monitor is the umbrella service, not a single log file or dashboard.
- Collecting data is not the same as retaining it forever. Configure data collection, destination, retention, access, and cost intentionally.
- An alert is a detector. An action group is the recipient or automation it invokes. Neither replaces an incident-response plan.
How it fits (diagram)
Diagrams courtesy of Microsoft Learn / Azure docs: azure-monitor/overview
Start small
Begin with the user-facing success signal, a few resource-health metrics, a destination for useful logs, and an alert that reaches a real owner. Test the alert and its action before relying on it in an incident. Add more telemetry only when it answers a decision or troubleshooting question.
Related
azure-monitor-metrics · azure-monitor-activity-log · log-analytics · kql · metric-alert · action-group · workbooks · application-insights · northwind-traders-case-study
📘 Source: Microsoft Learn — Azure Monitor overview, checked 2026-09-16.
Application Insights
What it is
Application Insights is Azure Monitor’s application-performance-monitoring feature. It collects evidence from inside a running application—requests, dependencies, exceptions, traces, and selected user interactions—so a team can understand what customers experienced rather than only what a server did.
Why it exists
Infrastructure monitoring (CPU, disk) tells you the host is fine but not why users are frustrated. Application Insights instruments the app itself to reveal request latency, error rates, failed dependencies (DBs, external APIs), and end-to-end distributed traces — the insight you need for debugging performance.
Key ideas
- Instrumentation sends application telemetry to Application Insights. For many code-based server applications, Microsoft recommends OpenTelemetry-based collection; the exact setup depends on the runtime.
- A request is work the application receives. A dependency is an external call it makes, such as to storage or a database. An exception records an error. A trace supplies diagnostic context across those operations.
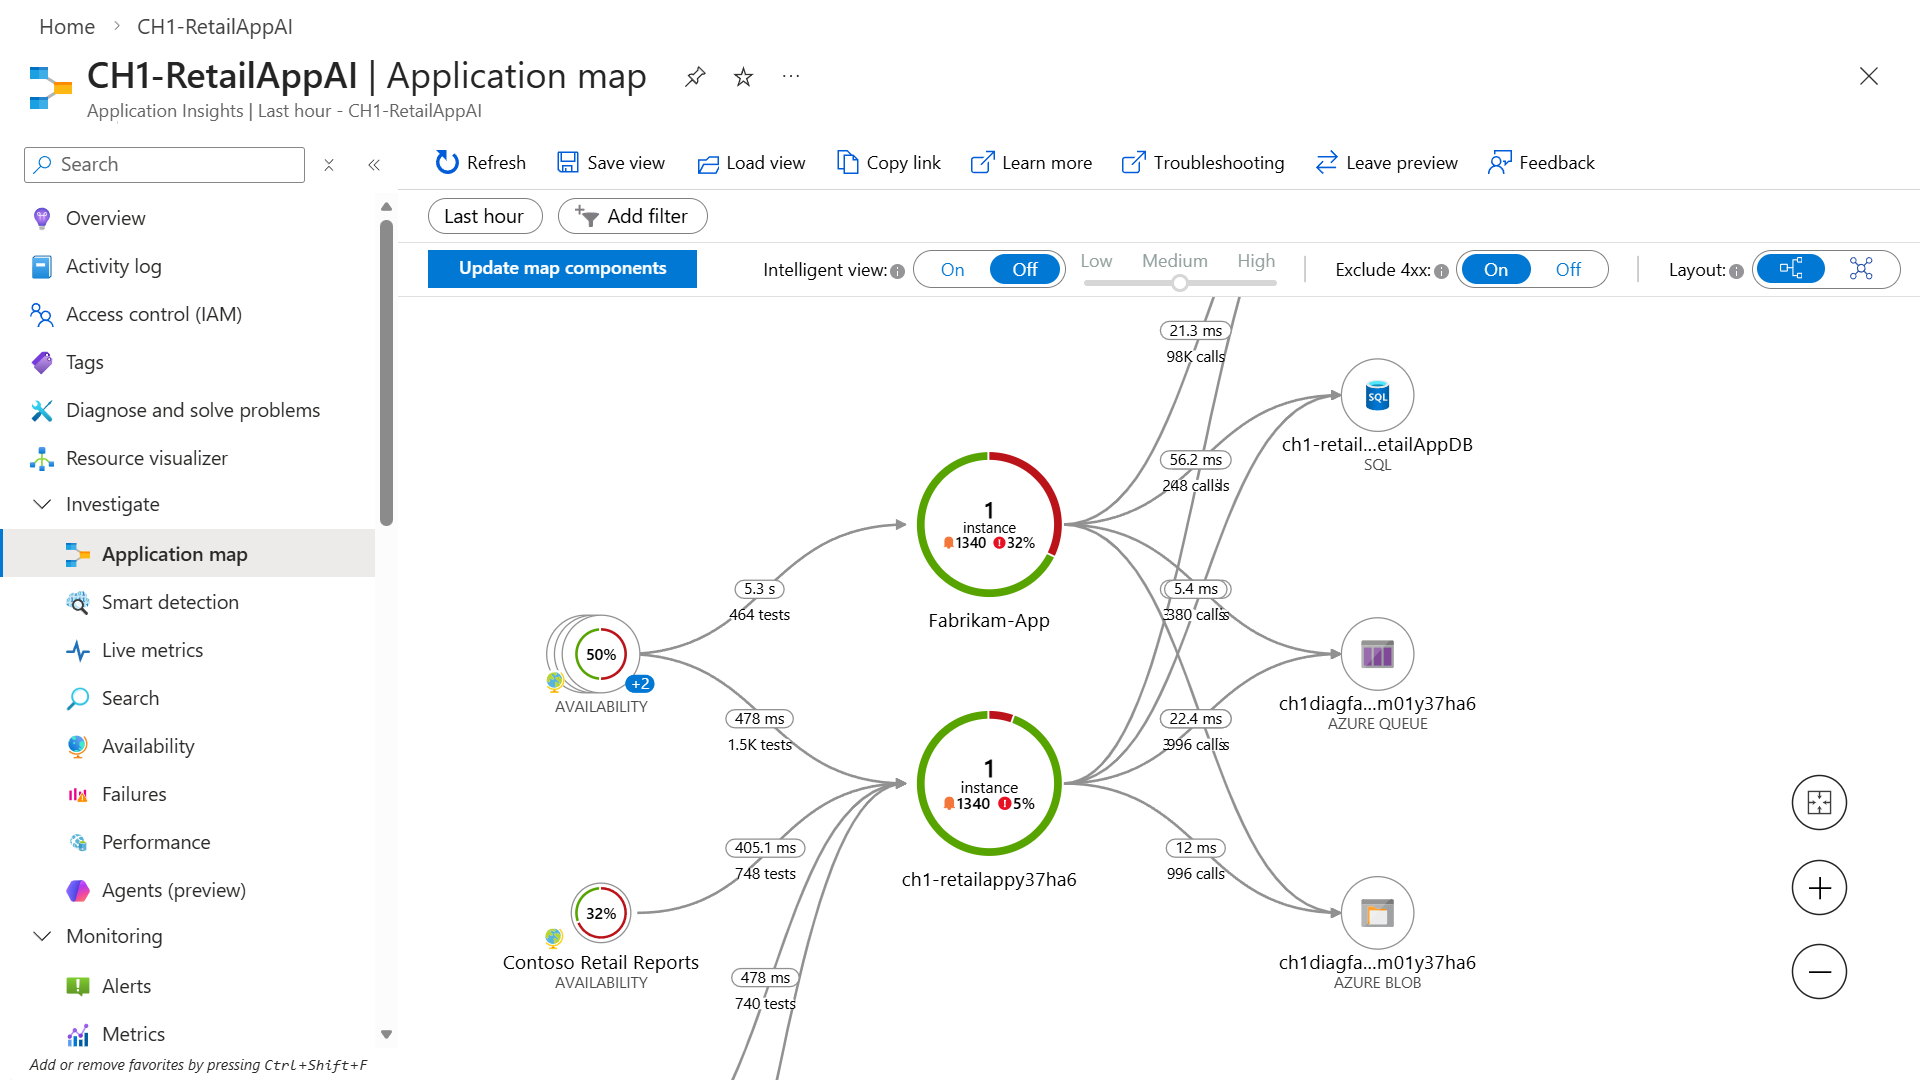
- Application Map and transaction views can show how components call each other. Log Analytics and KQL support deeper analysis where configured.
- Availability tests check an endpoint from outside the application. They are useful evidence of reachability, but do not prove every user journey or dependency works.
Northwind example
When a shopper cannot submit an order, Northwind looks in Application Insights. It can see the failed checkout request, the slow call to Blob Storage, the exception message, and correlated telemetry from the same transaction. A VM CPU metric alone could show that the VM was healthy while customers still saw an application error.
Common confusion
- Application Insights is not a substitute for Azure Monitor infrastructure monitoring; it is part of that wider platform.
- Instrumentation can collect sensitive information if configured carelessly. Choose what to collect, scrub sensitive fields, limit access, and set appropriate retention.
- A successful availability test does not prove a logged-in checkout, payment, or data path is working.
How it fits (diagram)
Diagrams courtesy of Microsoft Learn / Azure docs: azure-monitor/app/app-insights-overview
Where it appears in the route
Read azure-monitor first, then connect this entry to log-analytics, kql, alerts, and an application deployment.
Related
azure-monitor · log-analytics · kql · metric-alert · workbooks · northwind-traders-case-study
📘 Source: Microsoft Learn — Application Insights OpenTelemetry observability, checked 2026-09-16.
User & Reliability Signals
User Analytics
What it is
User analytics is the collection and analysis of how real users interact with an application — page views, sessions, funnels, retention, clicks, geography, device, and journey paths — to understand behavior and satisfaction. In an Azure context it is typically instrumented through Application Insights and powered by its telemetry + KQL queries.
Why it exists
Performance monitors tell you a server is healthy, but user analytics tells you whether people actually use and value the product. It exists to answer “are users getting value?” — which is the insight that drives product decisions and ties back into continuous feedback.
Key ideas
- Signals tracked: page views, sessions, users, click/feature events, funnel steps (where users drop off), retention over time, geo/device breakdown.
- Where it lives: App Insights Browser/usage telemetry and custom events, queried with KQL over the Log Analytics store.
- Workbooks/views: usage analytics render as funnels, cohorts, and date-range comparisons (not just raw KQL).
- User analytics answers behavioral questions (“what do users do?”) while feature usage answers product-adoption questions (“which features get used?”).
Exam notes
- Pair user analytics (behavior) with feature usage (adoption) — the exam treats both as the user side of continuous feedback.
- Know it’s instrumented via Application Insights and analyzed with KQL.
- The point of collecting it is to feed back into the backlog/planning (a feedback-loop), not just to display dashboards.
Related
application-insights · feature-usage · feedback-loop · continuous-feedback · telemetry
📘 Source: Microsoft Learn — User Analytics
Feature Usage
What it is
Feature usage is telemetry about how much and how often specific features or product areas of an application are used — tracking adoption, popularity, and drop-off of individual features so teams know what to keep, improve, or retire.
Why it exists
Not every feature ships to an audience. Feature usage exists to answer “do users actually use what we built?” It surfaces low-adoption or unused features, reveals which areas deserve investment, and validates whether a release achieved its intended outcome — closing the feedback loop.
Key ideas
- Tracked via custom events in Application Insights / telemetry (e.g. “button clicked”, “workflow completed”), or explicit feature-instrumentation flags.
- Pair with feature flags: ship a feature dark, measure usage, then roll it out fully or kill it based on adoption.
- Metrics of interest: active users per feature, usage frequency, conversion/drop-off within a feature.
- It is the product/adoption lens, complementary to user analytics (overall behavior).
Exam notes
- Feature usage is the “are features used?” signal that feeds decisions to keep / expose / retire functionality.
- Often tested together with feature flags as a way to release to a subset and measure adoption before full rollout.
- Instrument custom events in App Insights and query adoption with KQL into workbooks.
Related
application-insights · user-analytics · feature-flags · feedback-loop · continuous-feedback
📘 Source: Microsoft Learn — Feature Usage
Synthetic Testing
What it is
Synthetic testing (synthetic/active monitoring) is a technique that continuously generates scripted, simulated user traffic against a live application from external locations to verify availability, responsiveness, and key flows — even when no real users are online. In Azure it’s delivered by Application Insights availability tests (URL ping, multi-step, and standard tests).
Why it exists
Passive telemetry only tells you about real users’ traffic — if nobody is online during an outage, you won’t know until users complain. Synthetic testing exists to proactively verify the app is up and responding before users are impacted, by simulating requests from fixed global points on a schedule.
Key ideas
- Run tests from multiple global locations on a schedule (e.g. every 5 minutes) against URLs or multi-step flows.
- Availability tests in Application Insights: URL ping, standard test (combines request + dependency validation), and multi-step web test (a recorded user journey).
- Each test reports success/failure, response time, and location breakdown; failures can fire alerts via action groups.
- Complements passive monitoring: synthetic = proactive, telemetry = reactive/real-user.
Exam notes
- Synthetic testing = proactive availability monitoring; App Insights availability tests are the Azure implementation.
- Remember the three test kinds: URL ping (basic), standard (request + dependencies), multi-step (browser journey).
- Tests run from global locations → catches regional issues; successful results prove an endpoint is reachable and responsive, not that the app is bug-free.
- Commonly feeds status dashboards and alerts (the “is it up?” signal in the feedback loop).
Related
application-insights · azure-monitor · alerting · continuous-feedback · feedback-loop
📘 Source: Microsoft Learn — Synthetic Testing
Alerting
What it is
Alerting is the practice of acting when monitoring data indicates a problem. In Azure Monitor, an alert rule evaluates a signal and condition; when the condition is met, it creates an alert and can trigger an action group to notify people or start automation.
Why it exists
Telemetry in a dashboard helps only when someone is looking at it. Alerting turns a defined symptom into a timely response: it sends the right context to the people or automation that can investigate and reduce customer impact.
Key ideas
- An alert rule = resource(s) + signal + condition + action:
- Signal — metric (metric alert), log query (KQL), activity-log event, or App Insights condition.
- Condition/logic — e.g. CPU > 85%, error count > 5, URL unavailable.
- Action groups can notify by email, SMS, or push and can start runbooks, Functions, Logic Apps, webhooks, ITSM incidents, or other supported automation.
- Alerts can be stateful or stateless. A stateful alert can resolve after its condition clears; a user response such as Acknowledged is a separate operational record.
- Choose the signal before the rule: metric, log query, activity-log event, smart detection, or another supported alert type. Static and dynamic thresholds both need tuning against real workload behavior.
Northwind example
Northwind alerts when order API failed requests exceed a tested threshold. The rule creates one alert per affected resource and triggers an action group that pages the on-call team and opens an ITSM incident. The alert remains visible even if a maintenance processing rule suppresses the page. Maya acknowledges the alert while investigating; that user response does not change whether the underlying metric condition has resolved.
Exam notes
- An alert rule monitors resource data, evaluates a condition, and triggers action groups when it fires.
- Metric alerts use numeric time series; log alerts use query results; activity-log alerts use matching management events.
- Action groups centralize notifications and automation. Processing rules can add or suppress action groups after an alert fires.
Related
azure-monitor · metric-alert · application-insights · action-group · telemetry · synthetic-testing · feedback-loop
📘 Source: Microsoft Learn — Azure Monitor alerts